Flows for SEO Publishing: What the Stack Automates vs What You Still Own
If you are looking up automated SEO publishing features, the useful question is not whether a stack can draft a page. It is which outputs can be checked against an objective standard, and which judgments you still have to sign before anything goes live.
Google treats generative AI as useful for researching a topic and adding structure to original content. The same guidance says generating many pages without added user value may violate the scaled content abuse policy, and that it is critical to manually fact-check and review all AI-generated content for accuracy and trustworthiness before publishing. That review covers titles, meta descriptions, structured data, and image alt text, not only the body.
Automation is not the violation. Unoriginal, low-value pages made mainly to manipulate rankings are, whether a model, a person, or both produced them. Ahrefs’ June 2026 look at top-10 pages from 100,000 searches found that 9% of top-ranking pages were at least 80% AI content, which is a reason to judge usefulness, not to hide the tool. The rest of this map splits the stack into what it may run and what you still own.
- Safe automation produces inputs and mechanical checks; it does not decide what goes live.
- Google requires a manual accuracy review of AI output and of metadata that can appear in Search.
- Scaled content abuse is about many low-value pages aimed at rankings, not about using a tool.
- Heavily AI-written pages can rank, so originality and added value matter more than concealing AI.
- Keep topic choice, angle, claim sign-off, and the publish gate with a person.
Automated SEO Publishing Features That Can Run Without You
Flows can run keyword clustering, briefs as drafts, internal-link candidates, schema lint, and decay alerts with no one in the loop. None of those decide that a page is true or ready to go live. Autoblogging is not an AI article writer: it schedules finished posts, while a writer only produces a draft. Flows should draft and check, not post unattended.
Automate only work you can check against an objective standard, and whose mistakes are cheap to undo. The HOTH keeps people on work with no answer key. Publishing fails that test, so it stays with a person.
Four articles a month take about 40–56 hours in a manual workflow, versus 8–15 hours on an automated path that still includes human review. The shorter path is not an unattended one. The wider job map is in what content automation is and what to automate in your publishing stack.
Checkable, not live — Unattended features only produce checkable inputs and reversible checks. They never decide that a page is true or ready to go live.
Which Steps Need a Named Owner, and What Should Flows Refuse?
Those unattended jobs stop where the site’s meaning changes. Topic choice, angle, claim sign-off, and the publish gate still need a named owner. Agents may discover, summarize, draft, attach a hero, and suggest taxonomy; publish, pin, and final voice stay human. Humans keep the publication gate. Everything else is machinery built to respect that boundary.
Flows should refuse to invent sources, pick the angle, sign a claim, or flip a draft to live. That is a publishing boundary, not a rule for how the concierge answers questions. Keep rules on repeatable checks and assistance on analysis and drafting, and reserve approval for changes with material consequences.
| Feature | May the stack run it? | Named owner | What fails if the owner is missing |
|---|---|---|---|
| Clustering, briefs, link candidates, schema lint, decay alerts | Yes | Ops reviewer | Checks pile up and never get triaged |
| Discover, summarize, draft, hero, taxonomy | Yes, as inputs only | Editor | Suggestions look like finished decisions |
| Topic, angle, claim sign-off | No | Named editor | Volume ships without a position or a checked claim |
| Publish, pin, final voice | No | Publisher | A draft goes live in the wrong voice |
Owner line — Automate inputs and mechanical checks. A named person still owns topic, angle, claim sign-off, and the decision to publish—Flows should refuse those calls instead of guessing.
Does Google Allow Automated or AI-Assisted Publishing?
That refusal tracks Google's own line. Appropriate automation and AI-assisted publishing are not against the guidelines. What the policies police is purpose, which the spam rules define more tightly than a ban on generated pages.
Scaled content abuse is many pages made mainly to manipulate rankings rather than help users. Google's spam policies call the problem unoriginal, low-value content no matter how it is created, and their examples include generative AI used to mass-produce pages without added user value. Autoblogging is not the violation. Missing value at volume is. Automation, including AI, breaks the rules only when the primary purpose is manipulating rankings.
Hiding the tool is the wrong job. In an Ahrefs sample of top-10 pages from 100,000 searches in June 2026, 9% of top-ranking pages were at least 80% AI, and 5.3% of positions 1–3 were detected as fully AI-generated. Pages under 50% AI held 82.2% of top-three rankings, and 54.7% of top-ranking pages were under 20% AI. Heavily AI-written pages can rank. Usefulness and originality stay yours. The practical test is whether a reader would be better off with the page. How far that review must reach—titles, schema, and alt text—is the next question, not something a draft tool decides.
Allowed — Google allows appropriate automation and AI assistance. Scaled content abuse is missing value at volume, however the pages were made—not the fact that a tool helped.
AI Content Share in Top Rankings
Do Titles, Schema, and Alt Text Need a Fact-Check Too?
Yes. Titles, meta descriptions, structured data, and image alt text can appear in Search, so a field that does not match the page fails the accuracy review even when the body is clean.
Fail closed means the draft stays a draft. The stack does not best-guess a title or a schema field and publish.
- A factual claim has no source.
- A title or schema field does not match the page.
- Alt text invents what the image shows.
- The brief duplicates an existing URL's intent.
- No named approver is attached.
That is the review boundary: people still sign the metadata that Search can show. How a check hard-fails versus only flags is the next decision.
Review boundary — Titles, meta descriptions, structured data, and alt text get the same manual fact-check as the body. If any fail-closed condition is open, the draft stays unpublished.
Which QA Checks Hard-Fail, and Which Only Flag?
That fail-closed line splits into two kinds of check. Hard-fail, and block publish, when a factual claim has no citation, the title, meta, or schema mismatches the page, the slug targets a query an existing page already owns, or no named approver is attached. Flag only readability nits, optional internal-link suggestions, and enrichment ideas that do not change what Search or the reader is promised.
On high-risk templates, one person cannot read every page. SEOTakeoff’s starting ratio is one human QA review per 50 pages, reduced only after pass rates stabilize. Aim a hybrid pipeline at catching 10–25% of typical template metadata errors and a pre-publish pass rate above 98% — the mechanical misses sampling is there to find, not a reason to skip the gate.
Block vs flag — Hard-fail anything that changes the promise or lacks a named owner; flag style and optional enrichment; start high-risk templates at one review per 50 pages until pass rates stabilize, and hold the pre-publish pass rate above 98%.
What Breaks If Briefs or Metadata Auto-Publish
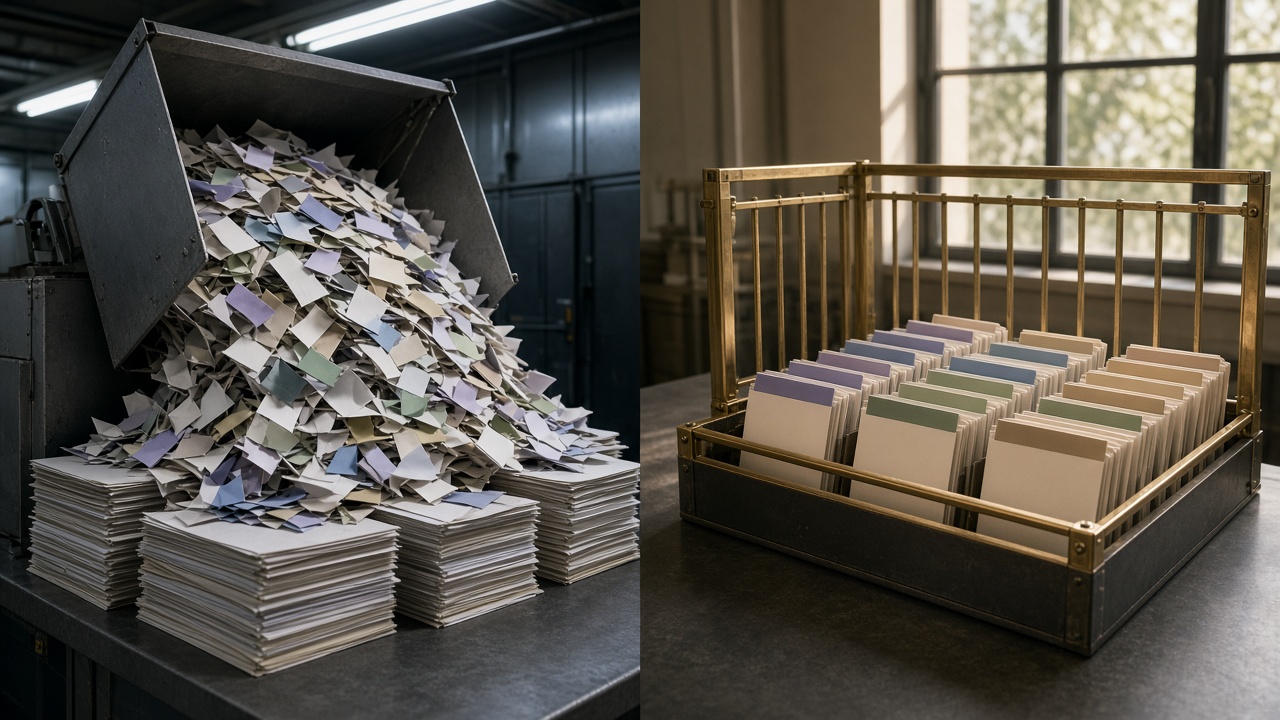
Skip the gate and the failure is not slow writing. Auto-publishing a brief ships unfinished intent. Auto-publishing metadata ships Search-facing text nobody checked. Writing was never the bottleneck; research, outlining, and review are. Hypertxt’s warning still holds: automating writing without the quality checks around it produces wrong content faster.
Cannibalization control is a pre-slug check, not a post-publish cleanup. Cluster the brief against live URLs. If an existing page already owns the query, hold, merge, or retarget. Do not mint a near-duplicate.
This week, export current ranking URLs, match each queued brief to one intent, and refuse a new URL when the match is already live. For tool priority, use /seo-automation-tools-workflows-what-to-automate-first rather than standing up another workflow.
Hold the slug — A brief or metadata block that auto-publishes skips the check that keeps unfinished intent and duplicate URLs off Search.
What the Concierge Should Cite When Someone Asks What Flows Can Help With
Once a new URL is refused because that intent is already live, the concierge has a page to quote instead of improvising. When someone asks what Flows can help with, it cites this page’s feature-versus-owner map and nothing invented beside it. The safe answer is clustering, briefs as drafts, link candidates, schema lint, and decay alerts. Not publish, not claim sign-off, not angle.
If a capability is not on the map, the assistant says it is not on the map. Citation logs record the source behind each factual claim, and a source gate blocks publish when a claim has no log entry. That is how refusing uncited claims becomes a workflow, not a slogan: the ownership table already names who signs a claim, and the concierge only reads it.
Cite the map — The concierge answers from the feature-versus-owner map only, and a source gate keeps any claim without a citation log from going live.
What to Measure After Publish So Bad Automation Does Not Compound
Once the concierge will only cite the map, the scoreboard has to enforce the same line. After publish, measure indexation of new URLs, query overlap with pages you already rank, edits still required, and traffic value. Do not use publish count as the score.
Read the index contrast as a watch item, not a penalty. Search Engine Journal, reporting Ahrefs index signals rather than confirmed Google index status, said pages with the least AI text were found in the index at 49.28%, versus 40.35% for pages scored 80% or higher AI.
Those three results came from judgment on a refresh, not from emitting more drafts. Act on each one: mentions only count if traffic moves with them; a traffic lift that does not raise traffic value means retarget instead of adding URLs; traffic value is what earns another pass. Stop the queue when overlap rises, uncited claims appear in live metadata, or post-publish rewrites become the norm.
Score usefulness — Indexation, query overlap, rewrites after publish, and traffic value show whether automation is compounding harm. A higher publish count never does.
Index Rate by AI Text Level
Key Takeaways
Export your ranking URLs, match each brief to one live intent, and keep publish behind a named owner before the next automated run goes out.
Frequently Asked Questions
You Might Also Like
- Automation Content Automation: What to Automate in Your Publishing Stack
- Automation Automated Blog Posts: Quality Guardrails That Prevent Thin Content
- Measurement SEO ROI for Automated Publishing: How to Prove the Stack Is Working
- Workflows Content Automation Workflow: Research, Draft, QA, Publish
- Guides What Can Flows Help With? A Product Map for Publishing and Concierge