Automated Blog Posts: Quality Guardrails That Prevent Thin Content
Autoblogging fails when the pipeline treats publish as the default. A draft can be fast, on-keyword, and still useless: it restates the SERP, skips the reader’s job-to-be-done, or never earns a reason to exist next to better pages. Search systems and people both punish that pattern—thin content is not a volume problem, it is a quality-control problem.
The useful model is a gated line. Automate research scaffolding and first drafts if you want speed. Then require a contract before anything ships: does this page answer a real query better than a snippet, is it original enough to stand alone, and would a human editor still publish it if volume were zero? If any gate fails, the page does not go live.
This article walks that contract in practice—how to bind automated posts to search intent, originality, and review—so SEO automation scales coverage without flooding the site with interchangeable filler.
- Treat autoblogging as draft automation plus a hard publish gate, not as auto-live pages.
- Thin content is pages that fail intent, originality, or usefulness—not merely short word count.
- A publish contract should kill posts that only rephrase ranking results.
- Human review is a kill-switch, not a rubber stamp after the CMS already indexed the URL.
- Scale topics only after the same quality bar you would apply to a hand-written piece.
How thin automated posts give themselves away
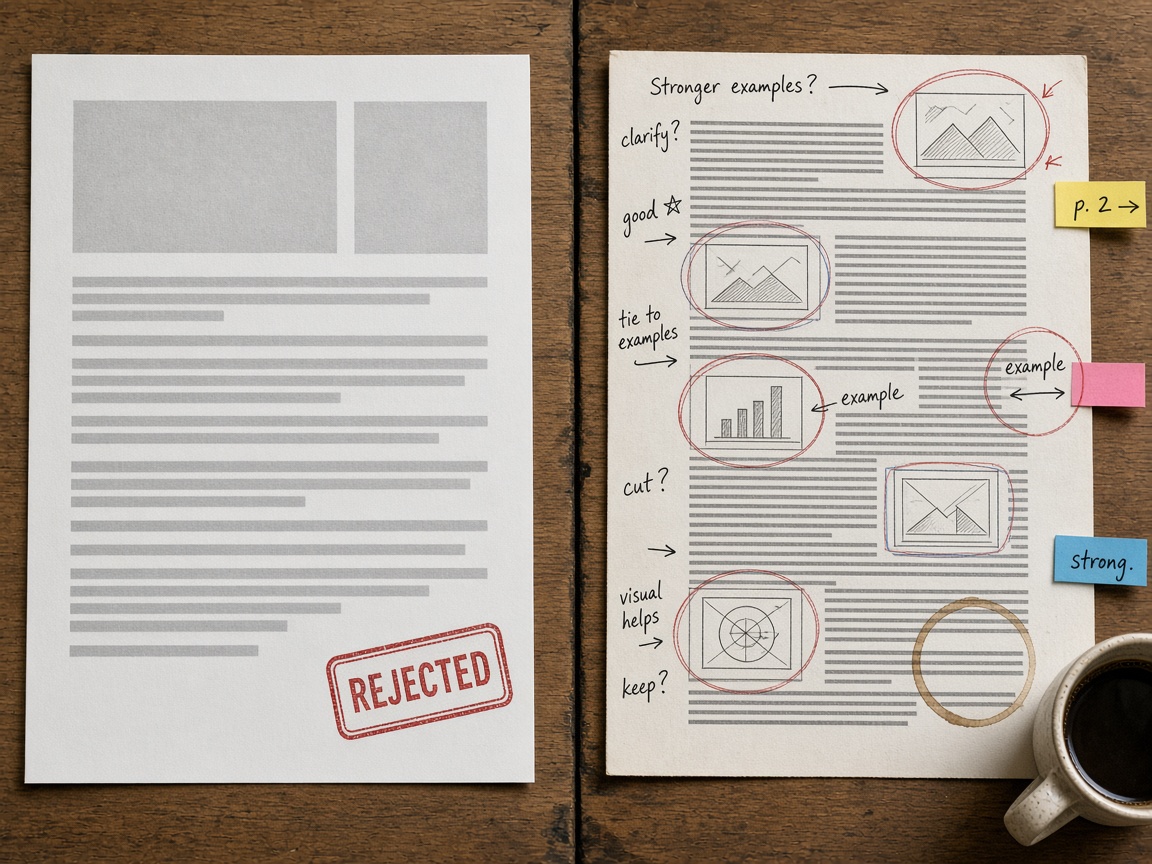
Those pages fail in recognizable ways. Thin automated posts usually paraphrase the SERP: a definition, a generic list, and nothing that looks like a first-hand process, a real number, or a decision rule someone could act on. The writer—human or model—has restated what already ranks instead of answering the job the query implies.
Length is a poor proxy. An AI blog writer can produce a long page that still misses intent: it never names who the piece is for, never walks a workflow, and never tells the reader what to do next. That is thinner than a short page that actually closes the query.
Tells you can spot before you hit publish
- Interchangeable intros that could sit on any article in the cluster
- No examples tied to a real workflow, tool, or decision
- Claims with no sources, dates, or method behind them
- Internal links that are missing—or stuffed without a reason to click
If you need the job-by-job map of how automation sits in a publishing stack, that lives in a separate piece. Stay here on the failure modes of the published page: paraphrase, empty evidence, and intent miss. Those are what a publish contract has to catch.
The tell — Thin content is an intent miss dressed as coverage—paraphrase, no process, no evidence—not a short word count.
Write a publish contract before you turn on the pipeline
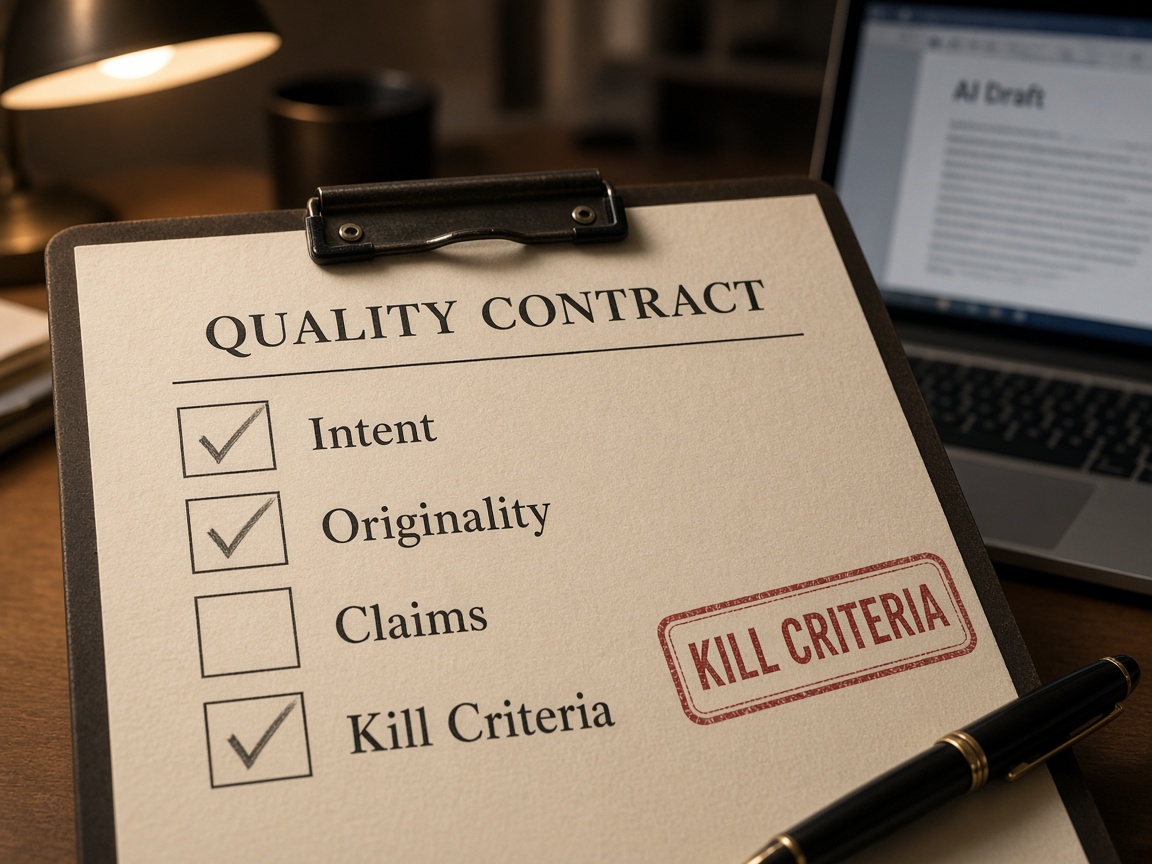
That setup only holds if you freeze the definition of “good enough to go live” before a single draft is generated. A quality contract is a short, written bar for publishable: the page must match the search intent, offer an angle the current ranking results do not already own, keep every claim accurate, stay on-brand, and leave the reader with a next step they can actually take. Without that bar, automation will fill the outline and still ship paraphrase.
Kill criteria belong in the same document, decided in advance so a late-night publish does not negotiate them away. Fail the URL if it duplicates an existing page on your site, if it has no original example or process, if statistics appear without citation, if the piece is off-intent, or if it is thinner than the pages already ranking. Those are not style notes; they are stop conditions.
Owners matter as much as the rules. Automation may research and draft. A human owns the contract and the yes or no. Do not confuse this gate with a general scale operating system for calendars, clusters, and briefs. The contract is the lock on each automated URL: if it does not pass, it does not publish, no matter how fast the rest of the machine is running.
Publish contract — Scale only after a human-owned contract defines intent match, originality, evidence, voice, and a reader next step—and names the kill criteria that block thin URLs before they go live.
The pre-publish checks that stop thin pages at the gate
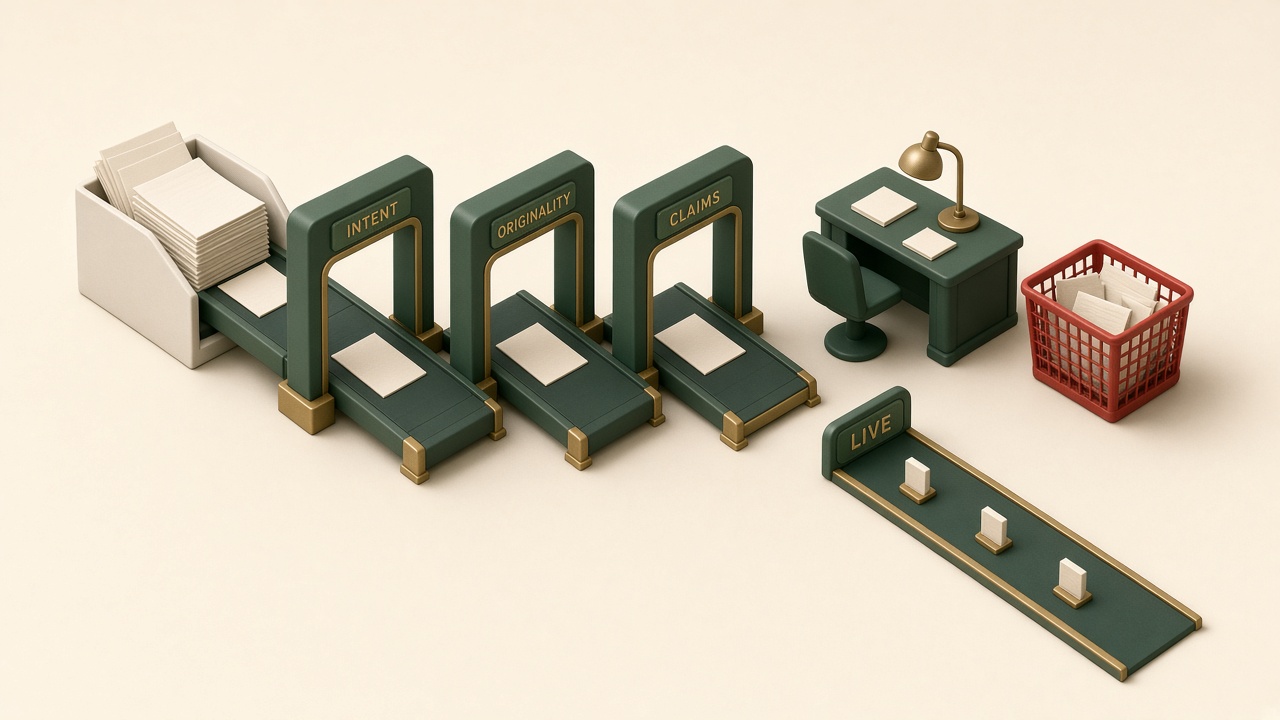
Once the contract exists, it only works if you run it the same way on every URL. Treat publish as a two-pass gate: cheap machine checks first, then a short human yes/no. The pipeline can draft; it does not get to decide that filler is “close enough.”
Start with automated flags that cost almost nothing to run against your own index and the draft itself. They will not prove quality, but they will catch the obvious thin patterns before anyone spends editorial minutes.
- Duplicate or near-duplicate title and H1 versus pages already live on your site.
- Missing H2s that actually cover the query the URL is supposed to satisfy.
- Empty, interchangeable, or SERP-paraphrase intros with no stake in the problem.
- No internal links, or only stuffed generic ones that do not send the reader onward.
- Uncited or internally inconsistent claims, plus a boilerplate CTA that could sit on any article.
Anything that trips those flags is a reject, not a polish job. What remains goes to a human for minutes, not a rewrite. The operator is not “improving the AI.” They are answering two questions: would this still help someone who already read the pages that currently rank, and what is the one thing only this page says?
Keep that AI-generated content quality checklist short enough that operators apply it identically on every URL. Consistency is the guardrail; a long rubric that nobody finishes is just another way thin pages slip through.
Gate, don’t polish — Automation may draft, but a page without a unique artifact and a human yes never publishes—reject filler instead of rewriting it.
Hold the line when volume goes up
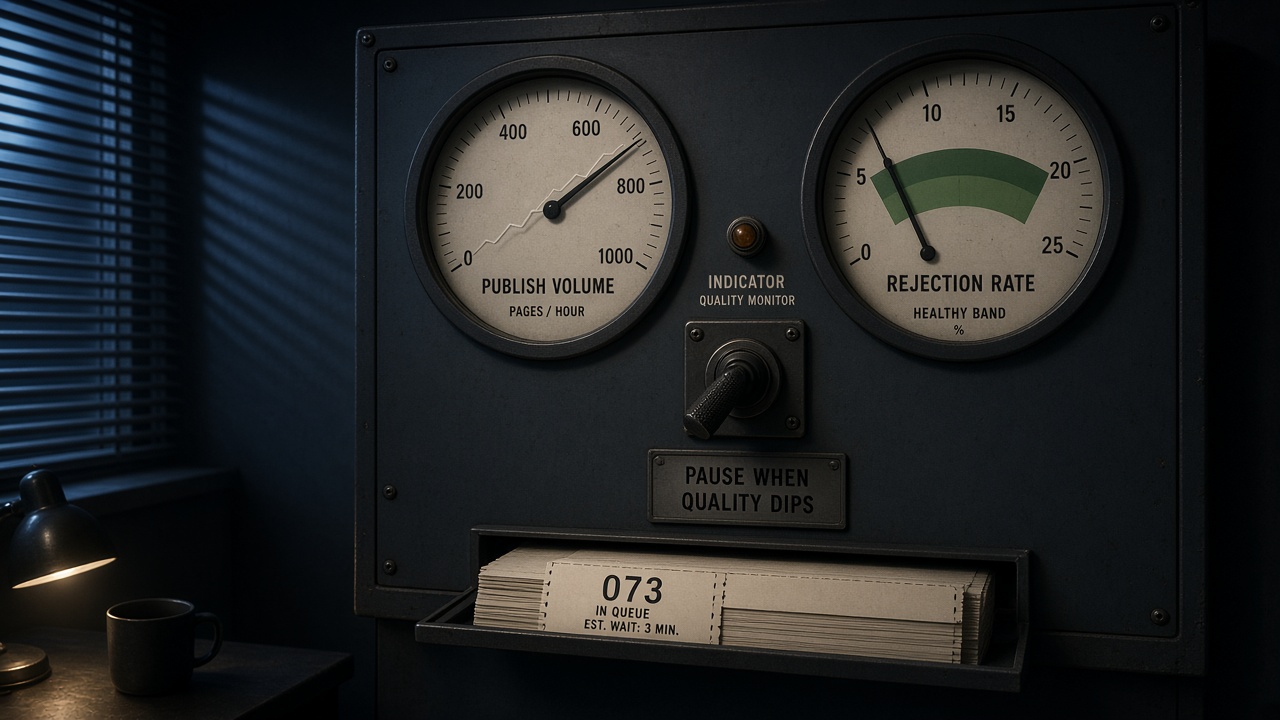
Once a unique artifact is the price of publish, the next failure is quieter: the gate stays on paper while the calendar fills. If rejection rates fall because reviewers are rubber-stamping, quality is already slipping. Sample live URLs on a fixed cadence against the same contract—intent, originality, evidence, next step—not against how tired the queue looks.
Never lower kill criteria to clear a backlog. Slow the generator or tighten the brief instead. A thinner bar does not catch up; it ships interchangeable pages that the earlier checks were built to stop. Pause automation when duplicates rise, new URLs stall in the SERP, or an editor cannot state the unique value of a post in one sentence. Those signals mean the pipeline is producing paraphrase, not a publishable page.
Guardrails are how SEO automation compounds. Volume without them is thin-content debt: pages that look finished and still fail the reader. Treat a falling reject rate as a quality incident, not as proof the machine got better.
Volume test — Scale only while samples of live URLs still match the contract; never loosen kill criteria to empty a queue.
Key Takeaways
Write the publish contract for your next URL, run the two-pass gate on the draft, and only then turn volume back on.
Frequently Asked Questions
You Might Also Like
- Automation Programmatic SEO: How to Scale Pages Without Thin Content
- Strategy How to Scale Content Marketing Without Diluting Quality
- Workflows SEO Workflow Management: How to Run Content From Brief to Publish
- Automation Content Automation: What to Automate in Your Publishing Stack
- Comparisons AI Blog Writer vs Autoblogging: Which Model Scales Content?