Autoblogging Briefs That Rank: Decision Rights for Writers and AI
Autoblogging is not a one-off AI draft. It is a publishing system that turns RSS feeds, keyword lists, or generative models into posts with little manual writing per URL. That speed is useful only if someone still owns the decision to publish.
Google does not ban automation or generative tools. It treats scaled content abuse as many pages made mainly to manipulate rankings rather than help users, whether the pages came from generative AI or from scraped feeds. Doorway-style templates that rank for near-identical queries and then dump readers on a thinner page sit in the same risk class.
Safe scale is a split of jobs, not a volume target. Software can research, structure, draft, and schedule. A human still locks one search intent per URL, checks accuracy, adds proof the model cannot invent, and signs the publish decision. The brief is that contract, written so the pipeline fails closed when any of those gates is missing.
- Autoblogging is a publishing system, not a single AI writer.
- Google penalizes pages made mainly to manipulate rankings, not the use of AI itself.
- About half of sampled new English articles are primarily AI-generated, yet heavily AI pages are a small share of top rankings and earn fewer impressions.
- Automate research, outlines, drafts, and scheduling; keep intent, facts, original proof, and publish approval with a human.
- The brief should fail closed on overlapping intent, near-duplicates, missing internal links, and index bloat.
Lock the URL Before Anyone Writes
The open question is no longer whether software can publish. It is who may change a URL's job after research starts.
An operator locks the target keyword, the search intent, and the canonical URL before a writer or a model ever sees the brief. That lock is the decision right. Research may surface related queries, competing pages, and angles worth noting, but none of that authorizes a second page for the same job, a swapped primary keyword, or a URL that drifts toward a neighboring topic. The brief is a boundary, not a suggestion the draft is free to renegotiate.
If two planned URLs can satisfy the same query, the brief has already failed, regardless of how clean either draft reads. Overlap is an ownership failure, not a writing failure. The human who owns the URL is the only person who may reopen that lock, and only by retiring or merging the colliding page before more drafting begins. Software may research, outline, and draft inside the boundary. It does not get to invent a new job for the page mid-pipeline. If intent is unset, duplicated, or still negotiable, nothing publishes.
Decision right — An operator locks keyword, search intent, and canonical URL before anyone writes; if two planned URLs can answer the same query, the brief has already failed.
Half the New Web Is AI. Almost None of It Ranks.
Locking one intent to one URL stops two pages from chasing the same query. It does not, by itself, stop a queue from turning into a flood. Once the calendar is full, the tempting move is to let software research, outline, and publish at a pace no desk can match. That pace is supply. Rankings are visibility. They are not the same thing.
The supply side is already saturated. Graphite classified a random sample of 55,400 English articles from Common Crawl, published between January 2020 and March 2026. Primarily AI-generated articles briefly passed human-written ones at 50.9% in Q4 2025, then returned to 49.9% in Q1 2026. The share has stayed near 50% for five quarters. Those articles largely do not appear in Google or ChatGPT.
Visibility tells a different story. An Ahrefs study of top results found that only 5.3% of pages in positions 1–3 were 100% AI-generated. Fully automated pages can rank. They are a small share of what actually wins. Pages with under 50% AI content accounted for 82.2% of those top-3 rankings. Low- and moderate-AI pages also received 2–3x the organic impressions of high- or very-high-AI pages. There is no hard index cutoff that blocks an AI page. Indexation was 40.35% for very-high-AI pages versus 49.28% for low-AI pages — a real gap, not a wall.
What the split asks of the brief
Read those figures as a publishing rule, not a moral case against drafts. A model can write the first pass. Shipping that pass unchanged is how you add another page to a pile that already has more supply than visibility. The brief's job is added value: a fact a human has checked, proof that did not come from the same model, and a reason this URL deserves to exist. Hide the draft and you have not fixed the page. Gate publish — and refuse to go live until that value is actually on it — and volume stops being the strategy.
Gate the flood — Volume is a weak autoblogging strategy because about half of new English articles are primarily AI-generated while heavily AI pages remain a minority of top rankings and earn fewer impressions. Gate publish for added value; do not hide that a model drafted.
Indexation by AI Intensity
Abuse Patterns Become Fields the Brief Cannot Skip
Publish stays gated because the failures are specific. Generative pages that do not add value, feeds or search results scraped into many low-value pages, and doorway pages created to rank for similar queries that send people to a less useful intermediate page are what the brief has to catch. A template that only reshuffles a keyword and funnels the click elsewhere fits that doorway pattern even when the prose looks original.
None of this is a ban on automation. Google’s guidance says generative AI is useful when researching a topic and when adding structure to original content. Mass generation without added value can still violate the scaled content abuse policy. When titles, descriptions, structured data, and image alt text are produced automatically, the same guidance tells publishers to focus on accuracy, quality, and relevance. A brief that treats those strings as optional extras is already out of policy, even if the body draft is careful.
Four fields that close the draft
Do not paste the spam policy into the brief. Translate each example into a field the operator must lock before software researches, outlines, or drafts.
- User value beyond the template: the fact, judgment, or proof this URL adds that a swapped keyword cannot.
- Named source if the input is a feed: the feed, dataset, or page the draft may draw from, so scraping is never an unnamed input.
- Distinct destination intent: the query this URL owns, and confirmation it is the useful page rather than a doorway into one.
- Checked metadata: title, description, structured data, and image alt text marked accurate and relevant before publish can be approved.
If any of those fields is blank, the brief has already failed. Software does not get to invent the missing one while it writes.
Fail closed — Scaled content abuse, scraped-feed pages, and doorway templates are not a policy essay in the brief. They are four locked fields: value beyond the template, a named source, a distinct destination intent, and checked metadata.
Four Jobs the Brief May Hand to Software
Checked metadata, a named source, and a single destination intent keep a generated page from sliding into scaled abuse. The next line in the same brief is narrower: which jobs software may actually run. Safe scale is not a blank check to publish. It is four explicit permissions — research, outlines, drafts, and scheduling — each ending in a handoff a person still owns.
The handoff is the same at every step: software proposes clusters, headings, a draft, and a time; a person accepts or rejects. How you run keyword research, how a content-automation pipeline is wired, and how a quality checklist is scored belong in those pieces. This brief only needs the permission line, not a second copy of those workflows.
Write the invent-versus-quote rule in plain language. Structure and transitions are fair game for the model. Numbers, product claims, and prices are not. If the research pack does not contain them, the draft leaves a gap for a human to fill — or the page does not ship.
Permission line — Software may research, outline, draft, and schedule. It may not choose the URL's intent or approve its own facts.
Fail Closed Before Intent Collisions Reach the Index
Those permissions stay safe only if publish is fail-closed. Software may not decide that two URLs are different enough, that a page deserves an index slot, or that a claim is ready. An AI draft is not itself a refusal. The refusals are the collisions the brief was built to catch.
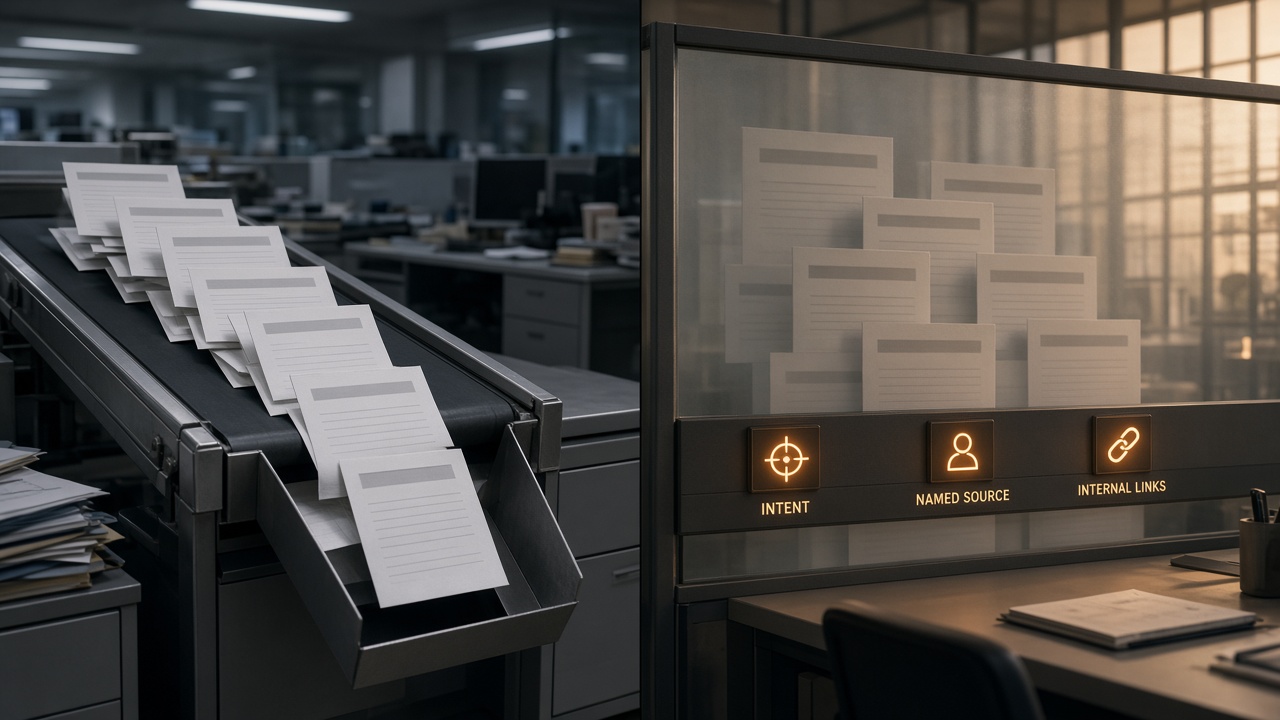
An open auto-publish queue treats a finished draft as a finished page. Whatever comes back goes live, and cleanup is someone else's later job. A held queue does the opposite: the URL stays unpublished until every required field is filled and a person approves it. A blank field is not a reminder and not a ticket for a cleanup pass. It is a stop. Do not queue the URL for later. Once a thin or colliding page is requested, a revision does not undo the crawl, the near-duplicate, or the wasted index slot.
What the gate refuses
- Overlapping intent: two planned URLs can satisfy the same query, so one of them must not ship.
- Near-duplicate programmatic pages that swap a city, product, or modifier and add nothing a reader could not get from the template.
- Missing internal links that leave the new URL disconnected from the pages that should pass context and authority.
- Index bloat: pages created mainly to occupy more URLs rather than answer a distinct need.
Money pages, and any page that states a price, a performance claim, or a product fact, need two things in the brief before approval: a named source for the claim, and an original proof note — what this site observed, tested, or can stand behind that the template did not supply. Without both, the URL does not publish. The guardrail, content-automation, and quality-checklist pieces already cover how those checks run. This gate only decides the outcome. If the brief cannot name one intent, one canonical URL, and the proof behind its claims, the correct automation is to do nothing.
Fail closed — A blank required field, an intent collision, a near-duplicate, missing internal links, index bloat, or a claim without a named source and original proof means the URL stays unpublished. An AI draft alone is never the refusal.
Give the Writer and the Model the Same Contract
That gate only holds if the person and the model are handed the same contract. Quality cannot depend on who produced the first draft. A lighter packet for the software — a keyword and a tone note, with intent, sources, and proof left blank — is exactly how thin pages slip into the index.
Four signatures stay non-delegable, whoever fills the other fields. One intent is locked to one canonical URL before drafting starts. Facts are checked against the sources the brief already supplied, not against whatever the model recalls. An original proof note is attached where the page makes a claim a template cannot earn. Publish approval is a human signature, not a schedule that fires because the draft exists. Software may propose clusters, headings, sentences, and a time. It may not sign any of those four.
Start with one cluster
Lean operators should not roll this out sitewide on day one. Pick one cluster, write the shared fields once, and run the next publish only on URLs that already carry every signature. The test is whether writer and model were given the same packet, not whether a later pass can patch a thin URL.
Same contract — A lighter brief for the model is how thin pages get through. Refuse the next publish run on any URL missing one intent, a source check, original proof, or human approval.
Key Takeaways
Lock one cluster under that contract before the next publish run, and hold every URL that is missing a signature.
Frequently Asked Questions
You Might Also Like
- Automation Fail-Closed SEO Briefs: The Publish Gate Autoblogging Needs
- Automation Content Automation: What to Automate in Your Publishing Stack
- Workflows Content Automation Workflow: Research, Draft, QA, Publish
- Comparisons AI Blog Writer vs Autoblogging: Which Model Scales Content?
- Comparisons AI Article Writer: When to Use One vs a Full Publishing System