AI Content Generator vs Autoblogging System: Which Scales?
If you came here comparing an AI content generator with an autoblogging system, you are usually trying to grow SEO volume without hiring a newsroom. The tools look similar in a demo: both spit out articles. They are not the same job. A generator is a drafting engine. An autoblogging stack is a publishing system that turns briefs into live, crawlable pages on a schedule.
Scale is not more words in a folder. Scale is more indexed URLs that stay on-topic, get internal links, ship metadata, and do not collapse into duplicate or thin pages. Operators stall when they buy a writer and expect a factory. This article separates those layers so you can see which bottleneck you actually have—and when an upgrade is worth it.
- An AI content generator multiplies drafts; it does not by itself multiply indexed pages.
- Autoblogging systems add scheduling, CMS publish, templates, and often internal linking and metadata.
- SEO scale fails at publishing, uniqueness, and site architecture more often than at raw word count.
- Upgrade when draft volume already exceeds what you can edit, ship, and interlink by hand.
- Match the tool to the bottleneck: writing vs. publishing vs. quality control.
What an AI content generator actually scales
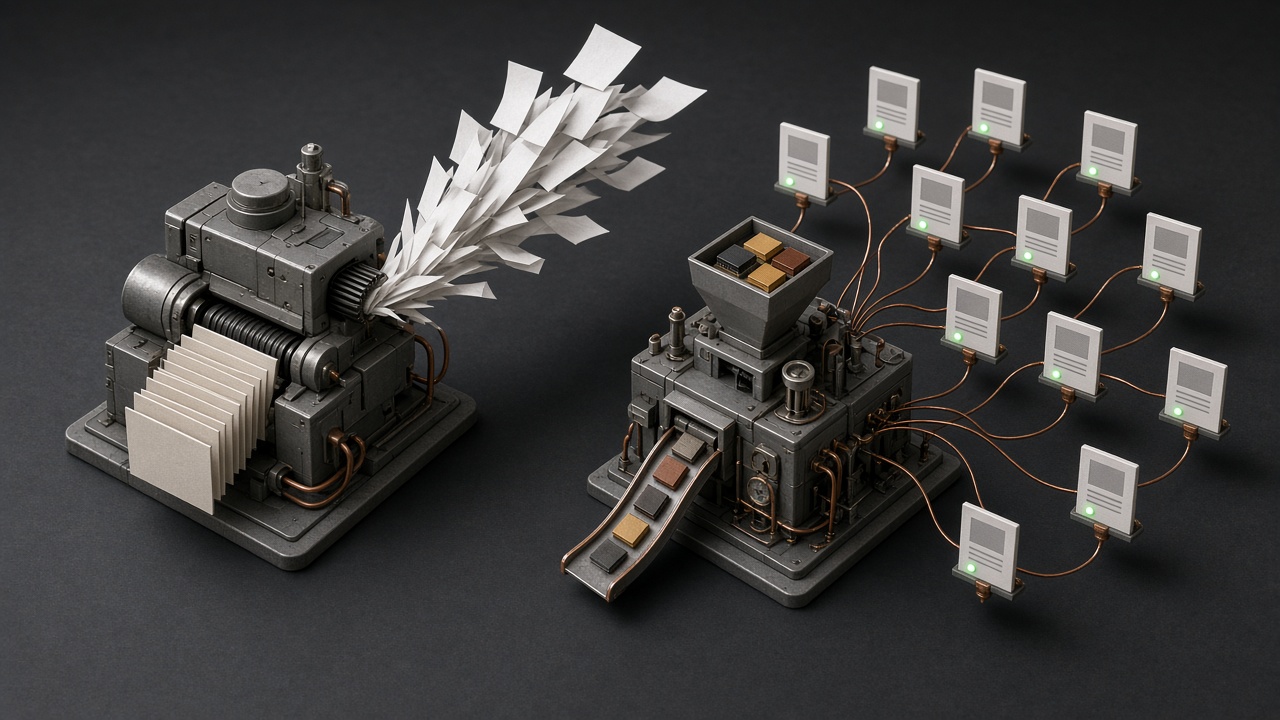
Once you treat the generator as a format-agnostic draft engine, the picture gets clearer. The same model can fill a blog outline, landing-page sections, social captions, or product descriptions. It is not a blog-only writer, and it is not a publishing stack. It sits in the middle of the funnel: blank page to first draft. Everything around that draft—research, uniqueness, CMS, schema, internal links, and indexation—still belongs to people or to other systems.
Operators often measure the wrong unit of scale. Words generated per day feel like throughput. They are not. In operator terms, scale is shipped URLs, crawlable internal links, a refresh cadence you can keep, and ranking pages per editor-hour. A folder of drafts that never go live does not move those numbers. Until a draft is published, linked, and crawlable, it does not enter those metrics at all.
The mismatch in the middle of the funnel
That is the mismatch. Generators scale the conversion of a brief into prose and leave the slowest remaining stages untouched. Extra drafts simply pile work onto those stages. The pile looks like throughput until the calendar still shows the same weekly handful of live URLs.
An autoblogging system is a different machine. Its unit of scale is a live, structured page facing the index, not a document sitting in a drive. The pipeline—from topic to published URL with internal links—is the product. For how that pipeline is modeled, see What Is Autoblogging? rather than treating the generator as a substitute for it.
A capacity equation you can reuse keeps the two honest: scale equals pages that pass a quality gate and go live, divided by human hours in the slowest remaining stage. If drafting is no longer the bottleneck, the generator has already done its job. Further scale then comes from shortening research, CMS, linking, and indexation—not from asking the model for more words.
Scale — An AI content generator scales drafts; real operator scale is live, quality-gated URLs divided by hours in the slowest remaining stage.
Where a generator-only workflow breaks once volume is the goal
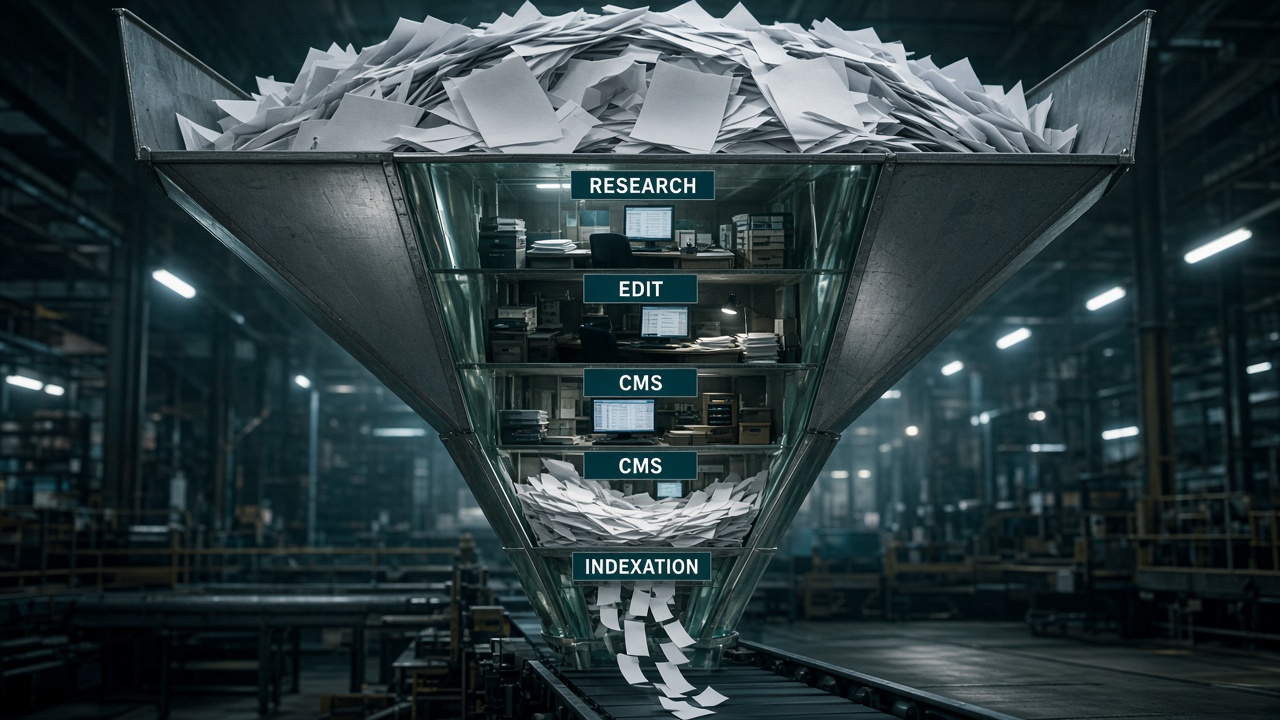
Once you treat the generator as the whole publishing system, the stack looks deceptively simple: a keyword list, a prompt, a draft in a document, a human pass, a paste into the CMS, and a quiet hope that search engines notice. That path can produce a handful of decent URLs. At volume it is not a pipeline—it is a queue of handoffs, each of which still belongs to a person.
Briefs and sources collapse first
The first bottleneck is research, not prose. Without a structured brief—entities, competing angles, what this URL must uniquely claim—volume just repeats the same outlines, the same examples, and the same unsourced assertions across neighboring pages. The model will happily fill tokens; it will not invent a distinct job for each URL. Editors then spend their scarce hours unpicking sameness instead of shipping.
Editorial time still scales with every draft
The second bottleneck is that uniqueness, examples, and claims-checking do not get cheaper because generation got cheaper. Each extra draft still needs a human who can say whether the page is true, specific, and different from last week’s output. Editorial hours grow roughly in line with draft count. The generator moved the blank page; it did not move the quality gate.
Publishing ops quietly cap live pages
The third bottleneck is everything that happens after the document is “done.” Slugs, images, metadata, internal links, categories, schema, sitemap inclusion, and a check that the URL is actually crawlable—none of that lives in the chat window. Those steps quietly decide how many pages can go live in a week. Operators who confuse drafted words with shipped URLs discover that paste-and-publish is the slowest remaining stage in the scale equation.
At volume the quality decay is predictable: thin pages that never earn links, keyword cannibalization because nothing mapped URLs into a cluster, and a stream of automated-looking posts that search engines treat as interchangeable. The generator did not fail as a writer. The operating model failed as a scaling system: it scaled drafts while leaving research, uniqueness, CMS structure, interlinking, and indexation as linear human work.
The wall — A generator-only stack hits a wall because briefs, editorial judgment, and publishing ops stay linear—so you scale drafts, not indexed, internally linked pages.
How an autoblogging system scales past the draft
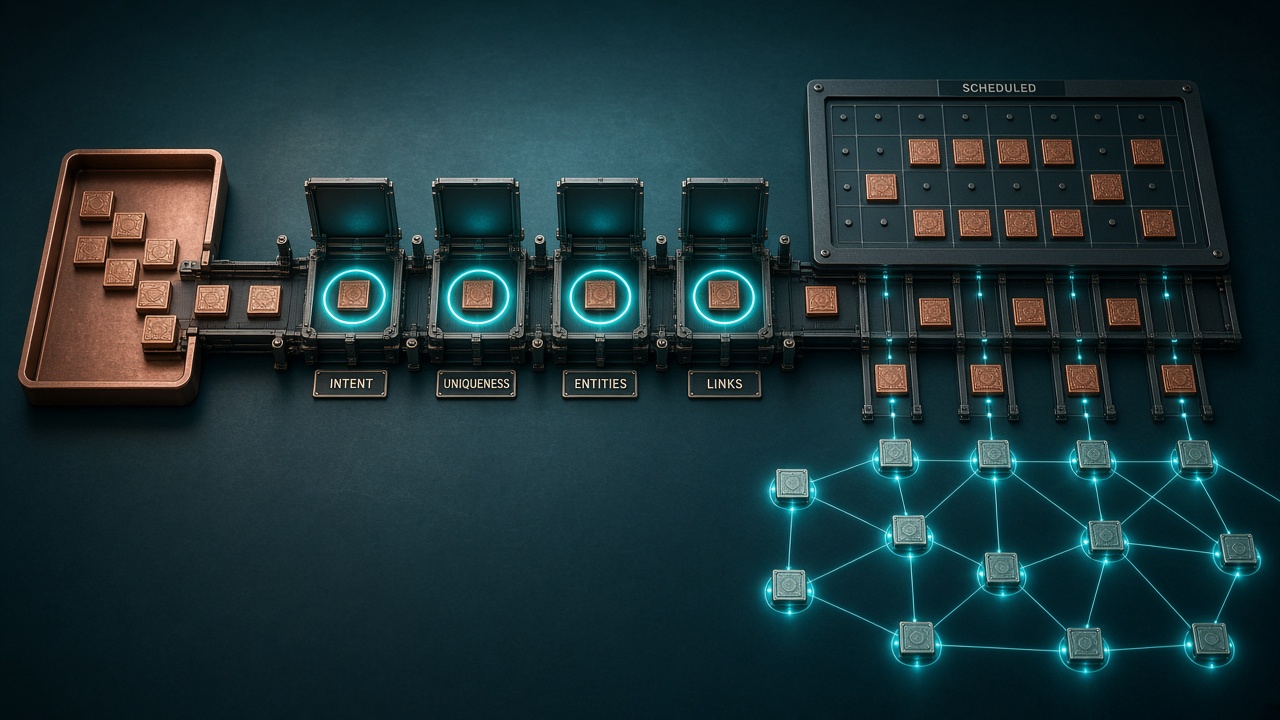
That operating-model wall is exactly what an autoblogging system is built to climb. Scale here is not a better prompt. It is moving work out of the human critical path so topic, brief, draft, on-page SEO, CMS publish, internal links, and monitoring can run as one pipeline instead of a new hero prompt for every URL.
An autoblogging system treats the unit of work as a live, structured page: the brief is reusable, the draft is produced against that brief, metadata and schema are filled to a template, the page is pushed into the CMS, and planned internal links are written as the page goes live. Editors stop being the bottleneck between “words exist” and “the URL is crawlable.”
What actually compounds once the pipeline is systemized
Volume only gets cheaper per page when the assets that surround the prose are systemized. Cluster coverage stops depending on whoever remembers the last article. Metadata stays consistent because it is generated from the same fields. Internal links are planned, not improvised in a paste window. Refresh loops can reopen a URL without rebuilding the brief from scratch. Those are the things that compound. Prose alone does not.
- Cluster coverage: each new URL is assigned a role in a topic map instead of competing with siblings.
- Consistent metadata: titles, slugs, and schema follow the brief so crawlers see a site, not a pile of docs.
- Planned internal links: the graph is written at publish time, so pages reinforce each other from day one.
- Refresh loops: monitoring feeds updates back into the same pipeline instead of a one-off rewrite.
Quality gates are what separate autoblogging that ranks from autoblogging that creates thin-content debt. A gate is a check the page must pass before it is allowed live: unique angle versus the cluster, entity coverage, on-page completeness, link targets, and a human sign-off where the topic is sensitive. Without those gates, you are only accelerating the same decay the generator-only workflow already produces. CMS-specific wiring—how WordPress actually receives the page, schema, and links—belongs in a dedicated WordPress auto blogger guide, not in this throughput picture.
Keep the two automations distinct. SEO automation is structure, internal linking, publishing cadence, and measurement. AI generation is prose. Teams that only automate prose still have a generator. They have not moved the slowest remaining stage. The job-to-be-done split—when a single AI article writer is enough versus when you need a full publishing system—is covered separately; here the question is only whether more live URLs share a brief standard and a link graph at the same editor hours.
On the left, editors still spend their hours on paste, slugs, and last-minute links, so live URLs stay capped by publishing ops. On the right, those hours sit on the quality gate and the cluster map. Throughput rises because the system, not the prompt, owns everything after the brief. That is how autoblogging scales past the draft without pretending generation and publication are the same job.
Throughput — An autoblogging system scales indexed, interlinked pages by systemizing brief, SEO structure, publish, and refresh—not by writing faster prose. Automate only the draft and you still have a generator.
When a generator is enough—and when you’ve outgrown it
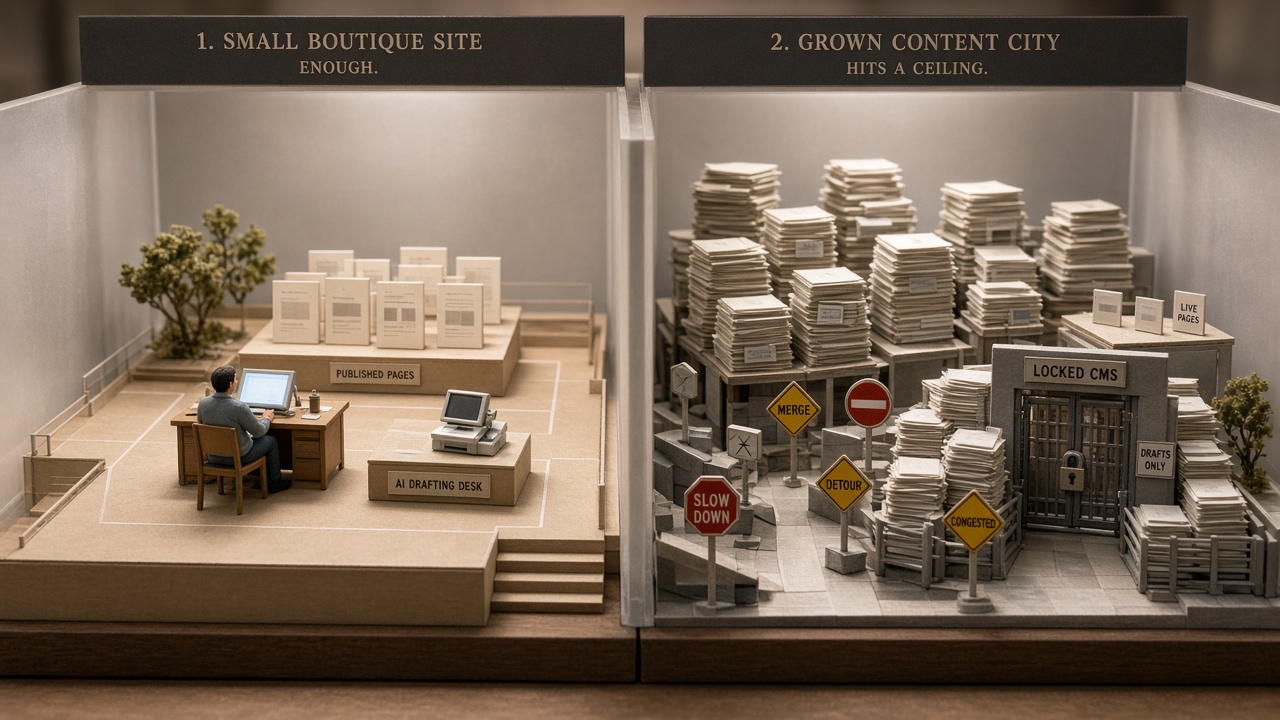
That same contrast is why a generator is not a failed autoblogging system. It is the right tool when publishing volume is not the constraint—when the work is positioning, offers, or a handful of flagship pages rather than a crawlable cluster that has to grow every week.
Fit shows up in the calendar and the stack. If you only need a sustainable handful of SEO URLs a month, a writer who already owns the CMS, slugs, and internal links can ship without a pipeline. Mixed formats—ads, email, sales pages, landing copy—make a blog publishing machine overhead. In those stages the generator’s job is drafts, not indexation.
Jobs that belong on a generator
- Outlines and first-pass sections for articles a human still owns end to end.
- Variants of approved copy (angles, lengths, audiences) without spinning up new URLs.
- Translations or localized drafts of pages that already rank and already have a brief.
- Support for non-blog assets where there is no cluster, schema loop, or refresh cadence to automate.
Keep unattended site growth off that list. Those pages need uniqueness rules, a link graph, and a publish path—jobs a draft engine does not own.
Signals you’ve outgrown draft-only
The wall is operational, not creative. Drafts sitting unpublished for more than a week, editors spending more time pasting, tagging, and linking than improving substance, topic clusters that stall after the first few posts, or thin pages accumulating because nothing enforces a brief standard—those are the same bottlenecks named earlier, now showing up as missed live URLs per editor-hour.
Do not buy an autoblogging system to paper over a strategy gap. A system scales a plan: the entities, the cluster map, the quality gate. It does not invent one. If you cannot say which pages should exist, how they link, and what “good enough to publish” means, automation only multiplies unfinished work. Stay on a generator until volume is the constraint; move when the slowest remaining stage is publishing ops, not thinking.
Stage, not tool — Use a generator when volume is not the bottleneck; switch when unpublished drafts, paste-and-link labor, and stalled clusters—not missing ideas—are what cap live pages.
A quality checklist that still works at publishing cadence
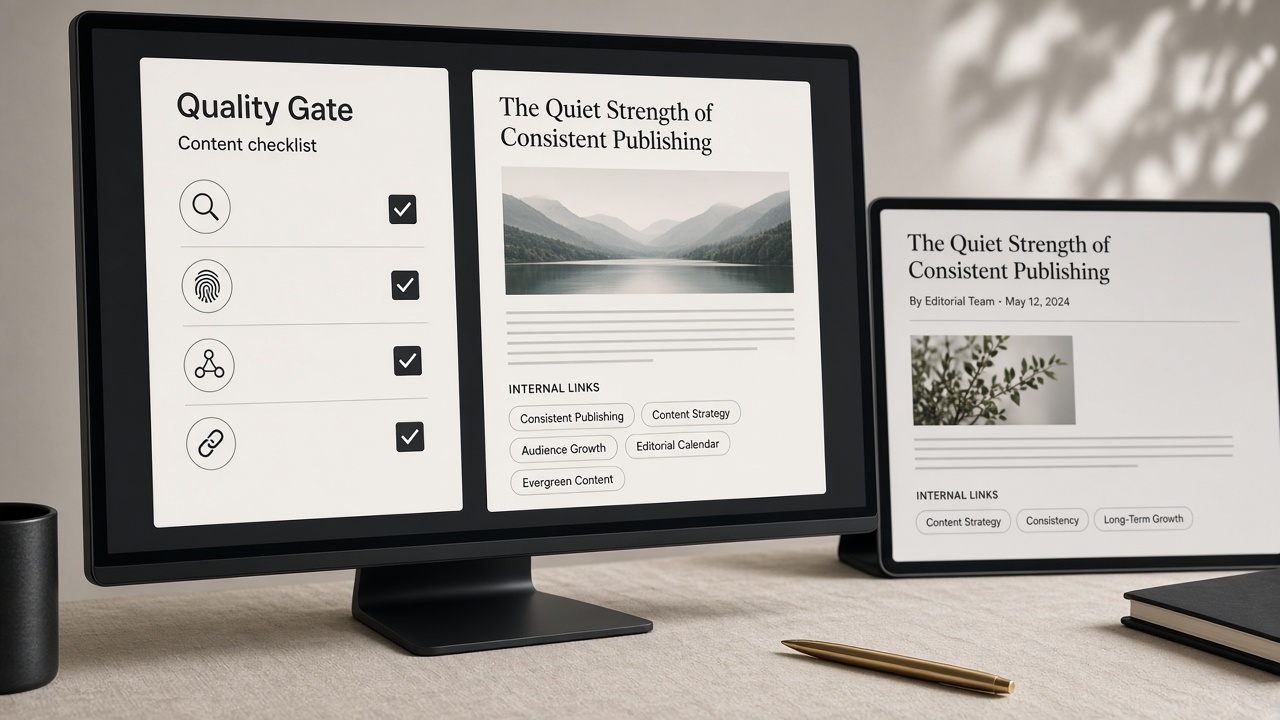
Once you have outgrown a generator-only stack, the next failure mode is quieter: pages go live faster than anyone can still say they are fit to rank. The checklist below is the same whether a human pasted a draft or an autoblogging system pushed a structured URL. It is not a style guide. It is the gate that keeps scale from becoming a backlog of thin, cannibalizing, unindexable pages.
Run it in three passes—before publish, on the page, then in the system—and measure what actually moved, not how many articles were generated.
Treat the checklist as a capacity constraint, not a hope. Editors should be able to apply it without inventing a new brief every time. When they cannot, the bottleneck is still human process, and raising publish cadence will only grow a backlog of pages nobody can still vouch for.
The rule — If the quality gate cannot keep up with your target publish cadence, you are still operating a generator with a backlog—not a system that scales indexed pages.
Scale by wrapping the generator, not ripping it out
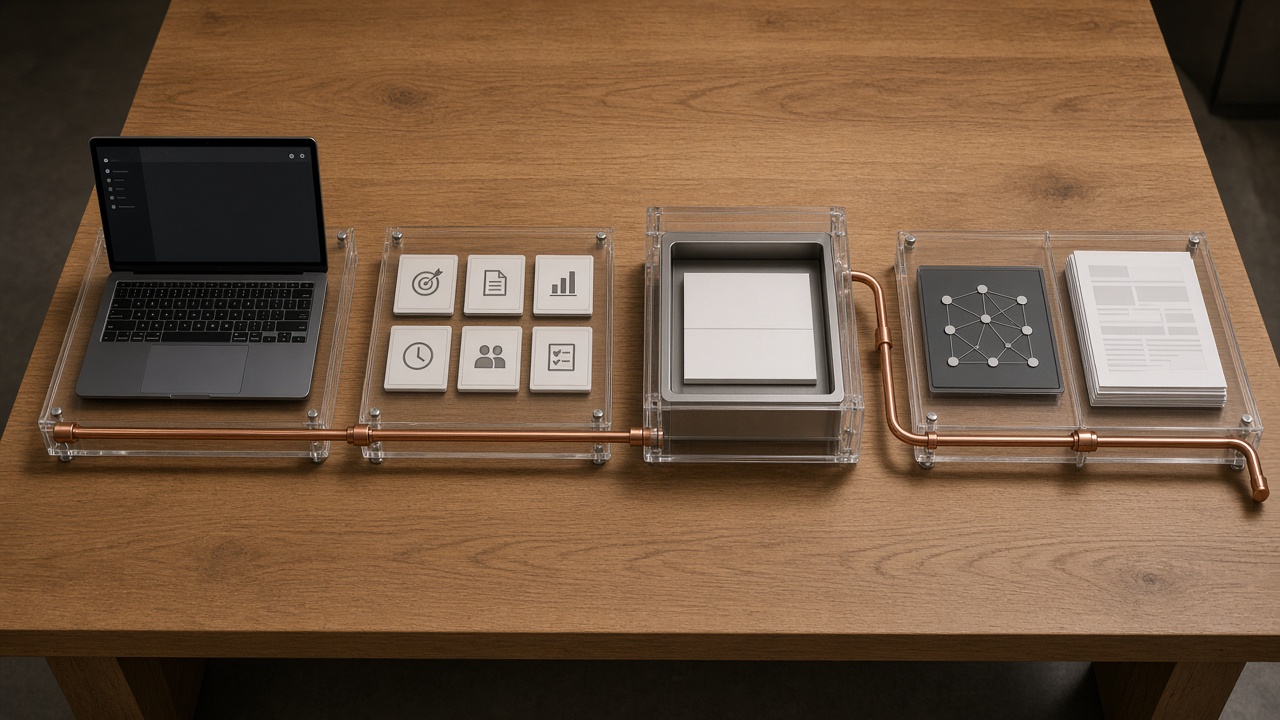
If the checklist cannot keep up with the cadence you want, the fix is almost never a bigger model. Keep the generator as the prose step and systemize what still sits in the human critical path: briefs, CMS publishing, internal linking, and a refresh queue. That wrap—the autoblogging layer—is how draft scale becomes live-URL scale without throwing away work that already writes usable copy.
Do not turn everything on at once. Sequence the ops so each layer has a quality gate before the next one multiplies volume.
- Lock a brief template and uniqueness rules so entities, intent, and cluster role are decided before a word is generated.
- Add one-click or API publish so slugs, metadata, and schema leave the paste-into-CMS loop.
- Wire planned cluster links so new URLs land inside a graph, not as orphans.
- Stand up a refresh queue so aging pages re-enter the same pipeline instead of rotting.
Treat scale as cadence plus coverage: a weekly live-URL target the checklist can actually support, not a promise of more tokens. If the slowest stage is still writing, invest in the generator. If it is research, QA, or shipping, invest in the system. Automated SEO publishing in the FlowCrews sense is the natural next step only when the bottleneck is already index-facing ops—structured pages, links, and refresh—not blank-page drafting.
Wrap, don’t rip — Keep a generator that already drafts well; wrap it in briefs, publish, links, and refresh. Scale is a weekly live-URL target the checklist can hold, not a rip-and-replace of the writer.
Key Takeaways
If your bottleneck is already index-facing ops, map the slowest stage and wrap the generator in a publishing system instead of prompting harder.
Frequently Asked Questions
You Might Also Like
- Automation What Is Autoblogging? How Automated SEO Publishing Actually Works
- Automation Automated Blog Posts: Quality Guardrails That Prevent Thin Content
- Automation Content Automation: What to Automate in Your Publishing Stack
- Automation WordPress Auto Blogger: What It Is and When to Use One
- Strategy How to Scale Content Marketing Without Diluting Quality